
Vibe coding has limits – your architecture shouldn’t
24. October 2026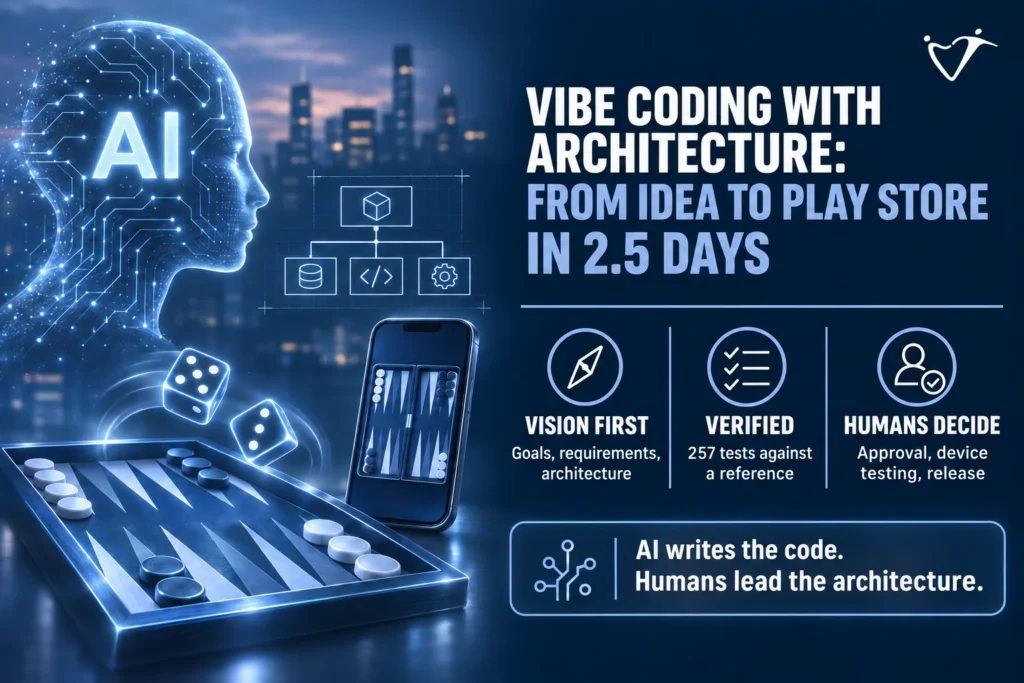
In October I published the article “Vibe Coding hat Grenzen – Ihre Architektur sollte keine haben” (vibe coding has limits – your architecture shouldn’t). The claim: AI speeds up writing code, but not architecture decisions. If all you do is prompt, you have a prototype after two hours and, after three months, a system nobody understands anymore.
A claim is easy to write down. So a week later I demonstrated the approach on a real project that was meant to actually ship: a backgammon app for Android, Windows and the web. With a computer opponent in three strengths, a 3D board, a leaderboard and dice statistics. No ads, no account, no tracking. The app is an open source project under GPL-3.0: the complete code, together with vision, requirements and architecture, is on GitHub. Every claim in this article can be checked there.
The result: about 2.5 working days passed from the first line of the vision to submission to the Play Store. A week later version 1.1 followed, in German and English, with feedback from players. AI wrote almost all of the code. It did not make the decisions.
Who does what
The most important question came before the first line of code: what does the AI take on, and what stays with me? The results of every row are documents in the repository.
| Task | Me | AI assistant |
|---|---|---|
| Vision and product | Target group, positioning, guiding principles | Market research, drafts, counterarguments |
| Requirements | Decide what applies and in which order | Phrase, number, link |
| Architecture | Make and approve every decision | Propose options, check against earlier decisions |
| Code | Review, accept, correct course | Write it, following fixed rules |
| Tests | Define what is checked against which reference | Write and run tests |
| Device testing | Play, record findings, involve testers | Turn findings into requirements |
| Release | Legal texts, store account, signing, approval | Build bundles, generate store graphics |
The guardrails for the AI live in a file in the repository that is loaded in every session. One concrete example: when an architecture decision is made, the AI updates the architecture in the same step and records the rationale in the decision log. On top of that, every task names its requirements and every test name carries the requirement.
The result is traceability you can follow step by step in the repository (documents in German), here using the obligation to use both dice:
Requirement A-107 “Both dice must be used if possible” → task T2.4 “Calculate legal moves” → decision in the log “The move generator returns complete moves, because the obligation can only be checked across the whole roll” → code → test “A-107: Both dice – expected: if only one order works, it must be played”
That keeps the AI fast and every decision traceable.
Six steps, even at AI speed
The October article describes six stations from backlog to delivery. I went through exactly these stations, just in hours instead of weeks.
1. Vision. Before any code was written, it was clear who the app is for and how it differs from the big free apps with ads and coins. The biggest risk was the graphics, so the board prototype came first. A short SWOT analysis of GNU Backgammon, one of the strongest free engines, concluded: don’t build it in, use it as an independent reference for the tests.
2. Roadmap. The project is split into deliveries, each a working intermediate result: foundation, board, rules engine, playable game, computer opponent, release. The same definition of done applies to every task.
3. Requirements. About 100 numbered requirements, including quality goals such as “fair dice” or “no storage in the browser”. Every task names the requirements it implements, as shown above with A-107.
4. Automated tests. 257 test cases. Every test name states the requirement and the expected result, so the test list reads like an acceptance protocol. Since I am no backgammon expert, the tests check the move generator and evaluations against reference data from GNU Backgammon. Missing domain knowledge is safeguarded rather than glossed over.
5. Human testing. Automated tests show that the app calculates correctly. Whether it is fun only shows when you play on real devices. One finding read: “Not a single win against Easy. That’s no fun.” It turned into a requirement, a change to the engine and a measurement. A beginner-level player now wins 46% instead of 15% of games.
6. Release. Signed app bundle, internal testing in the Play Store, privacy policy and legal notice per platform and language. Privacy is proven, not just claimed: the release bundle was checked for permissions, advertising ID and tracking libraries. The code is open source on GitHub under GPL-3.0.
Measure, don’t guess
One thing convinced me in particular: AI delivers suggestions quickly, but only measurements show which ones hold up.
- The three playing strengths were measured over 300 games each. Hard beats Medium in about 60% of games.
- An elaborate look-ahead over the opponent’s replies sounded good but did not reduce the error. It was removed again.
- Automatic bear-off now needs 13.1 instead of 15.5 rolls on average and avoids a backgammon where possible: 0 instead of 48 in 1,000 test races.
Rules for the codebase are tests too: no visible text is hard-coded, every text is translated, the legal texts match across all languages. Even the Play Store screenshots are generated as a test from the real user interface.
What isn’t perfect
Honesty is part of it. There was no code review by a second person; the reference engine, device testing and testers from my circle took on that role. The rule “game logic knows nothing about the user interface” is part of the architecture but not yet checked automatically. Tools such as ArchUnit or deptrac, which I mentioned in the October article, would be the next step. And the project was not strictly test-driven: tests and code were usually written in the same step.
What this means for your projects
AI makes software development dramatically faster. But the project also shows where the speed comes from: not from skipping vision, requirements and architecture, but from having done that work first. AI can only run fast in a direction someone has set.
Three takeaways:
- Think first, then prompt. Vision, requirements and architecture were done in one morning and made every later session faster.
- Write the guardrails down. Rules that apply in every session work better than good intentions in a prompt.
- Decisions and approvals stay with people. The AI proposes, checks and writes. Accountability stays human.
Vibe coding has limits. With guided architecture, they move a long way.
See for yourself: the app is available on Google Play, as a web version right in your browser and for Windows. The source code with vision, roadmap and decision log is open on GitHub.
Are you using AI in software development, or planning to, and wondering how requirements, traceability and approvals survive, especially with ASPICE or other process models in mind? As an ASPICE assessor with many years of process experience, I am happy to take a look at where you stand. Get in touch for a free 30-minute conversation.

